
Suggested tools for you
Choosing where to serve a model is rarely just a GPU decision. API breadth, deployment choices, billing mechanics, and the amount of infrastructure your team must manage all shape the day-to-day experience. We compared 99 tools for the top cloud platforms for ai workloads in inference, then put the 10 most relevant options up front for a faster shortlist. The leading choices span unified inference APIs, GPU clouds, and platforms that pair serving with fine-tuning or workflow tools; the right pick depends on how much control you want and what you need to run.
Quick trust line
Tools reviewed: 99 platforms in this category; 10 featured in detailed reviews
Last checked: November 4, 2026
Reviewed by: aitop10.ai software rankings editor
What we checked: Inference fit, model and hardware access, deployment approach, pricing signals, and practical limitations
Atlas Cloud

- Developers serving multiple AI modalities through one API
- Starts at From $0.01/PIC (Z-Image-Turbo LoRA)
- Usage signal: 929.1K
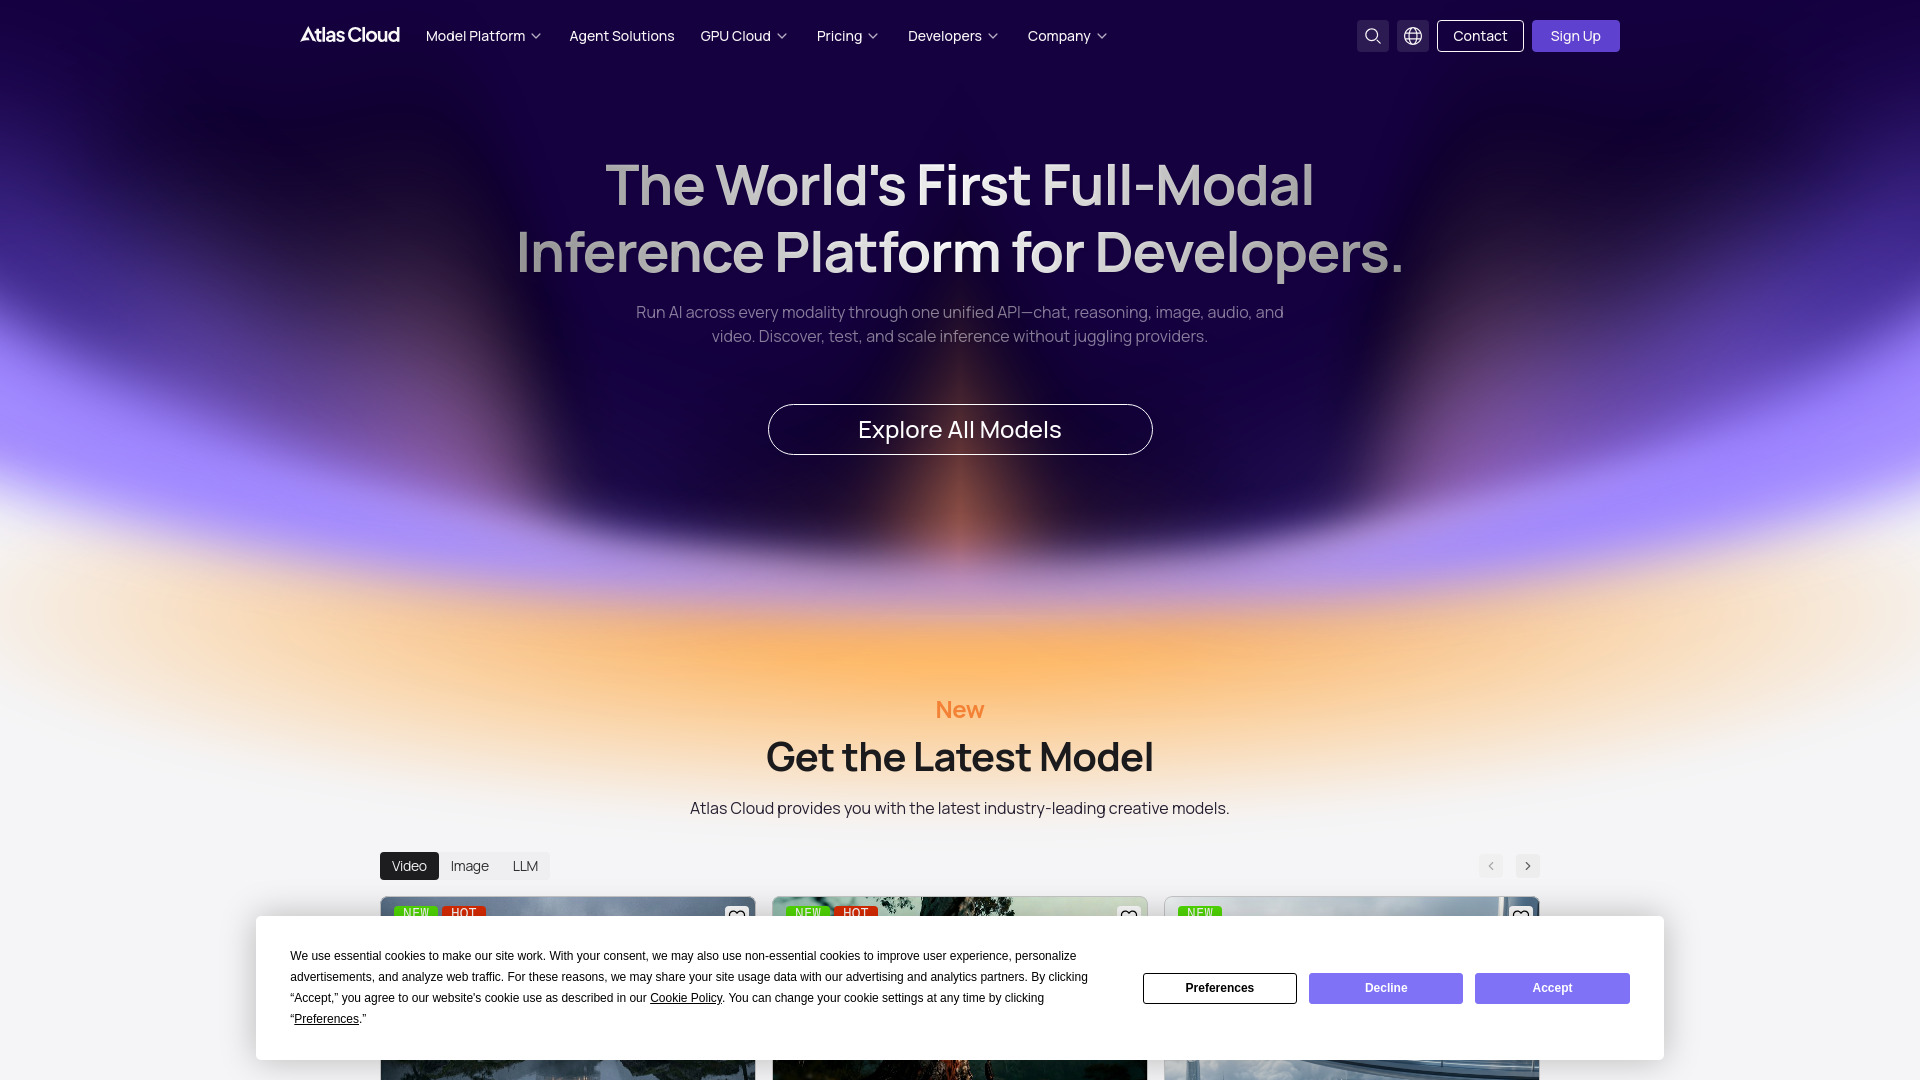
Atlas Cloud earns the first spot by putting several inference workflows behind one interface. Its unified API covers chat, reasoning, image, audio, and video, and the platform advertises access to more than 300 models. That breadth is useful when a product team is testing different model families or expects its workload to expand beyond text.
The trade-off is that this is infrastructure for developers and teams building on inference, not a turnkey no-code app builder. Usage-based billing can also be harder to forecast than a flat subscription: the listed starting point is $0.01 per PIC for Z-Image-Turbo LoRA, while actual costs depend on what you run.
Why it ranks first
| Score factor | Why it matters here | Platform evidence |
|---|---|---|
| Inference coverage | Lets teams serve varied product features without stitching together separate providers | One API for chat, reasoning, image, audio, and video |
| Model choice | Makes evaluation and switching easier across model providers | More than 300 models listed |
| Developer fit | Works best when teams want API-led access and deployment support | Positioned as an inference and model infrastructure platform |
| Cost clarity | Usage billing rewards monitoring, but needs active budget controls | Consumption-based pricing; listed entry price is task-specific |
Best fit
Developers building products that combine text and media inference.
Teams comparing models through one API before committing to a narrower stack.
Projects that need a broad model catalog more than a simple fixed subscription.
Limitations
Less suitable for nontechnical users who want a polished, no-code workflow.
Token- or GPU-based usage needs monitoring to avoid budget surprises.
The listed $0.01/PIC price is tied to a specific offering, not a universal inference rate.
Nebius AI Cloud
- AI developers scaling workloads on NVIDIA GPUs
- Starts at NVIDIA H200 GPU: $2.30
- Usage signal: 1.0M
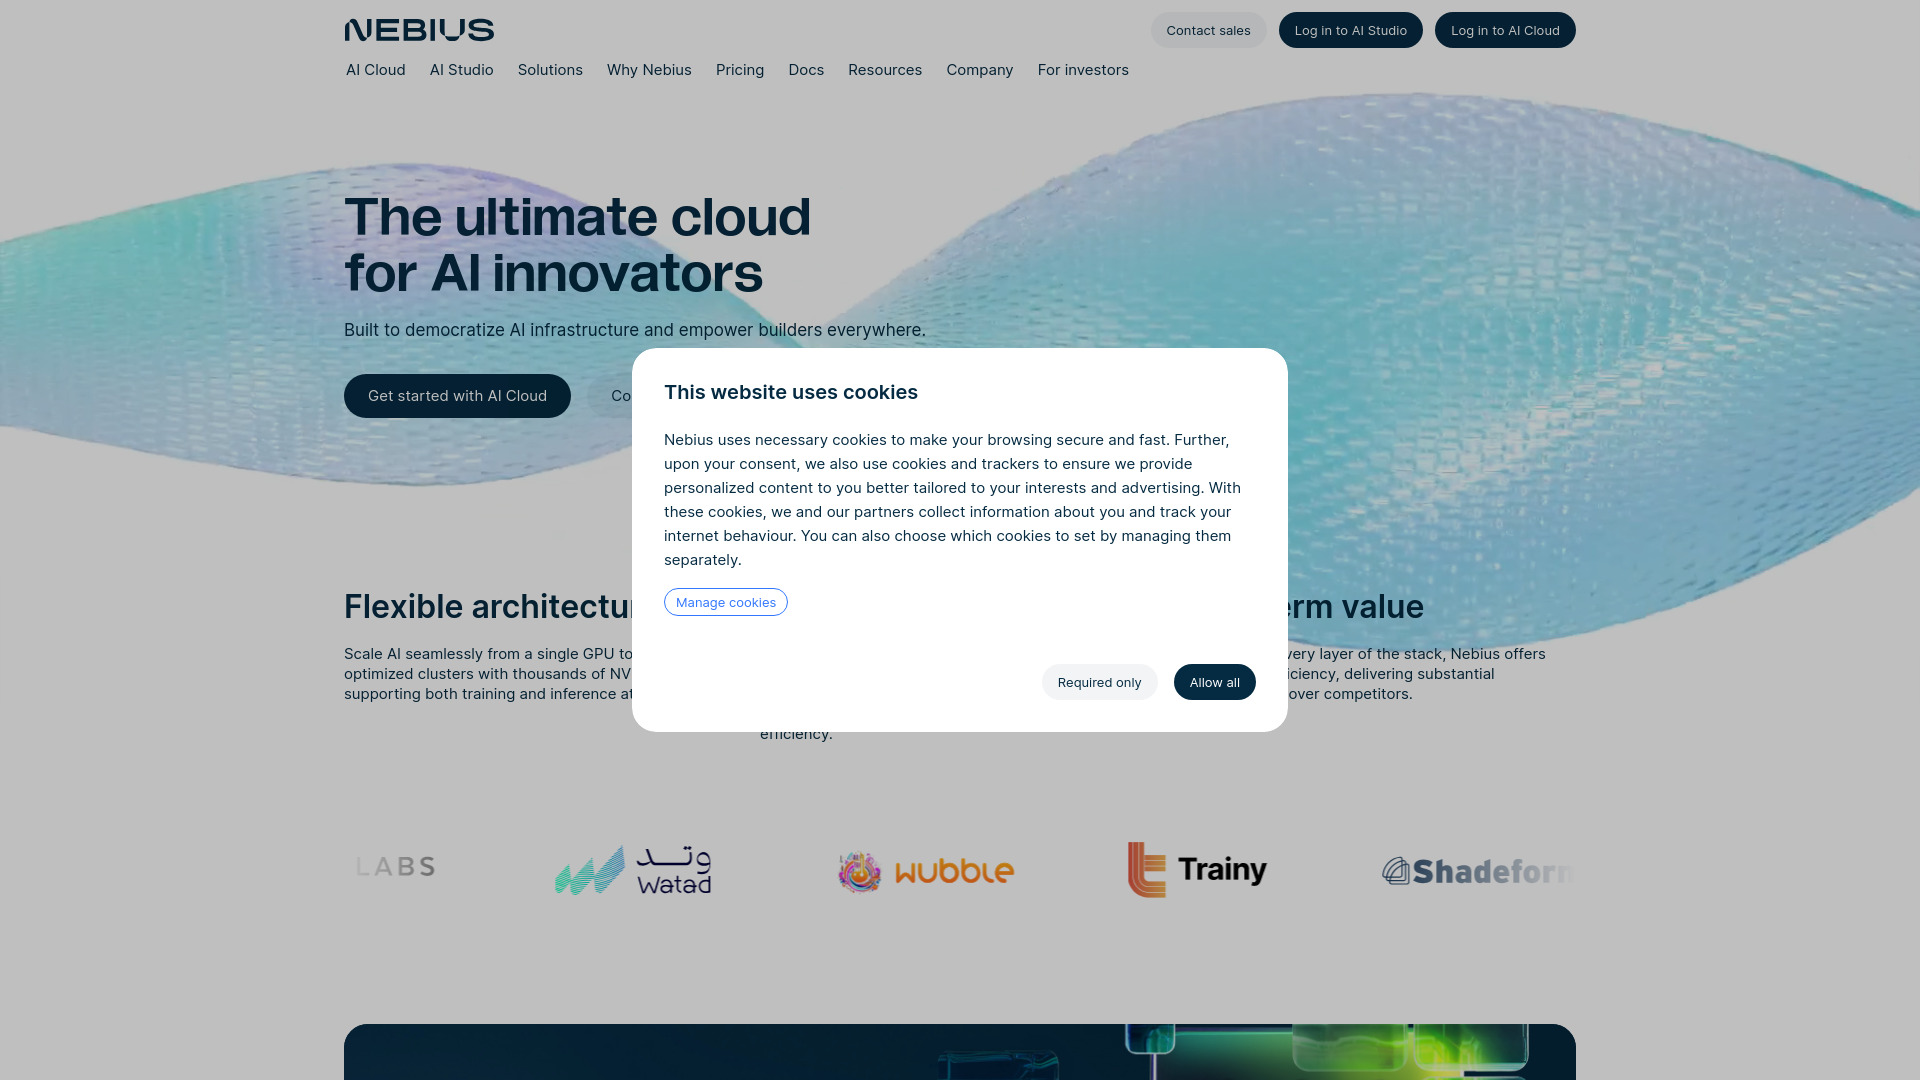
Where Atlas Cloud emphasizes a broad model API, Nebius AI Cloud puts more weight on the compute underneath a workload. It offers preconfigured NVIDIA GPU accelerators and high-performance InfiniBand, with a flexible architecture intended to scale AI jobs. AI Studio adds a model fine-tuning path, making the platform relevant to teams that need more than inference alone.
That combination makes Nebius a compelling choice when GPU capacity and the ability to tune models matter alongside serving them. It does ask for more infrastructure fluency than a managed API. Configuration-specific pricing can vary, and teams managing infrastructure as code should expect to take ownership of setup and operations.
Why it is near the top
| Score factor | Why it matters here | Platform evidence |
|---|---|---|
| Compute access | GPU availability is central to latency and throughput planning | Preconfigured NVIDIA GPU accelerators |
| Cluster networking | Can matter as workloads and deployments scale | High-performance InfiniBand is listed |
| Model lifecycle | Helpful when serving is part of a build-and-tune workflow | AI Studio supports fine-tuning |
| Operational effort | Flexible infrastructure offers control but raises the setup bar | Requires technical expertise with infrastructure as code |
Best fit
AI developers who want GPU infrastructure with room to scale.
Teams that expect to fine-tune models as well as run inference.
Workloads where access to NVIDIA accelerators is a major selection factor.
Limitations
Less attractive if you want an inference endpoint without managing infrastructure.
Configuration-specific costs need checking before you estimate production spend.
The H200 starting-price figure should be verified against the exact configuration and billing terms.
Deep Infra
- AI developers deploying models through a simple API
- $10 in free usage per month
- Starts at Check vendor pricing
- Usage signal: 502.3K
Deep Infra is the practical, API-first option in the podium. Its pitch is straightforward: run machine-learning inference through a simple API, scale the infrastructure as needed, and pay for usage rather than committing to a fixed-size setup. That shape can make experimentation easier, especially for developers who want to get a model-backed feature working before investing in their own serving stack.
The free monthly usage allowance is a useful way to test a workflow, but it does not remove the billing setup requirement: users may need to add a card or prepay. Usage tiers and invoicing thresholds are worth understanding before a prototype becomes a production dependency.
Best fit
Developers who want to connect a model through an API without building a full serving stack.
Teams validating demand before reserving GPU capacity.
Projects where usage-based billing is preferable to paying for idle infrastructure.
Limitations
A payment method or prepayment may be required to use the service.
Usage tiers and invoicing thresholds deserve a close read before scaling.
Pricing for a specific workload should be confirmed directly with the vendor.
Together AI

- AI developers combining inference with model tuning
- Starts at Check vendor pricing
- Usage signal: 998.2K
Together AI is worth a look when inference is only one stage of the work. Its offering combines a serverless API for open-source models with dedicated endpoints for custom hardware deployment, plus LoRA and full fine-tuning. That gives developers a path from quick model access toward a more tailored deployment without treating each step as a separate platform decision.
The flexible route comes with a technical workload of its own. Custom deployments and fine-tuning demand more configuration than a plug-and-play API, and pricing for large-scale custom setups or newer GPU configurations may require a sales conversation. If you only need a basic endpoint, some of this breadth may be unnecessary.
Best fit
Teams that want inference and fine-tuning in the same platform.
Developers serving open-source models who may later need dedicated hardware.
Projects that need a choice between serverless access and custom deployment.
Limitations
Advanced fine-tuning and deployment options require technical expertise.
Pricing for some large-scale GPU and custom configurations requires direct contact.
It may be more platform than a small project needs for one model endpoint.
RunningHub
- ComfyUI users running and publishing cloud workflows
- Starts at Check vendor pricing
- Usage signal: 4.3M
RunningHub takes a workflow-first route rather than presenting itself as a general-purpose model API. It provides a cloud-based ComfyUI environment where users can edit and run workflows online, then publish AI apps. For teams already comfortable with ComfyUI, moving execution to cloud GPUs can make workflows easier to access and share than keeping everything tied to a local workstation.
This focus is also the main caveat. RunningHub makes the most sense when ComfyUI is already part of your process; it is not the obvious choice for a team that wants a conventional inference API or managed language-model endpoint. Runtime costs should be checked before frequent or heavy use.
Best fit
Creators and developers who already build in ComfyUI.
Teams that want to edit, execute, and share cloud-hosted workflows.
Users interested in turning a ComfyUI workflow into a published AI app.
Limitations
You need familiarity with ComfyUI to get the most out of it.
Runtime use may add costs; check the current terms for your workflow.
It is less aligned with teams seeking a general inference API for production services.
BytePlus

- AI engineers building enterprise multimodal systems
- Free image and video tokens
- Starts at Bandwidth: $11.50/month/Mbps
- Usage signal: 4.3M
BytePlus brings model access and cloud infrastructure into a broad enterprise-oriented offering. Its tools span text, vision, speech, image, and video, and its AI Playground lets teams try models and solutions before building around them. The platform also covers infrastructure for training, serving, and scaling AI workloads, which may appeal to organizations trying to keep multiple parts of an AI stack under one provider.
The breadth is more convincing for engineering and enterprise teams than for a solo developer seeking one simple endpoint. Some products require contacting sales for full access, and the listed bandwidth-package price is not a direct measure of what inference itself will cost. Treat the free image and video tokens as a way to explore, not as a complete production-cost estimate.
Best fit
Enterprise teams evaluating multimodal tools across several modalities.
AI engineers who want a playground alongside training and serving infrastructure.
Organizations consolidating related AI services under one cloud provider.
Limitations
The platform is geared toward technical and enterprise buyers.
Full access to some products involves a sales conversation.
A bandwidth subscription price does not tell you the full cost of an inference workload.
RunPod

- Startups renting GPUs or scaling serverless inference
- Starts at MI300X from $2.49/hour
- Usage signal: 2.7M
RunPod gives teams two useful ways to get compute: rent GPUs on demand through GPU Cloud, or use Serverless GPU for scalable machine-learning inference. That flexibility is appealing to startups that want hands-on control while they experiment, then need a route to scale without immediately committing to a large managed cluster. Support for common AI frameworks such as PyTorch and TensorFlow helps fit it into familiar development workflows.
The experience depends in part on the instance you choose. Community Cloud performance can vary, so it is important to validate the exact configuration against your latency and reliability needs. Some advanced features also require contacting sales. Compare the cost of rented capacity with your expected utilization rather than choosing on hourly price alone.
Best fit
Startups that want on-demand GPU access without a long-term cluster commitment.
Developers who need a choice between rented GPUs and serverless inference.
Teams already working with PyTorch, TensorFlow, or similar AI frameworks.
Limitations
Community Cloud instances may not deliver uniform performance.
Advanced features can require a sales conversation.
GPU rental is not automatically cheaper if capacity sits idle.
fal.ai

- Developers serving diffusion and generative media models
- Starts at Check vendor pricing
- Usage signal: 3.2M
fal.ai is the specialist pick for teams working with diffusion models and generative media. It offers inference and training APIs alongside UI Playgrounds, so developers can explore a model before integrating it into a product. If your workload centers on image generation, a platform tuned to that category may be a more direct fit than a general-purpose GPU cloud that leaves model-serving choices entirely to you.
The specialist angle narrows its advantage: it is less compelling when your priority is a broad general-purpose compute environment or unrelated model families. Costs vary by model and usage, and some models have custom pricing. Check the current rate for the model and request pattern you intend to deploy.
Best fit
Developers integrating diffusion or other generative-media inference.
Teams that want APIs and a playground for testing models.
Projects that may need training APIs as well as hosted inference.
Limitations
Pricing can change with model choice and usage; some models have custom rates.
It is a narrower fit for workloads outside its generative-media focus.
Confirm latency and cost against your own request volume before launch.
ClearML

- AI teams managing GPU resources and deployment workflows
- Free for 3 users; 100GB storage; 1M API calls/month
- Starts at Check vendor pricing
- Usage signal: 51.5K
ClearML approaches inference from the operations side. Its Infrastructure Control Plane helps manage GPU resources, while its AI Development Center supports model development and testing; the GenAI App Engine adds an option for LLM deployment. That makes it useful when the challenge is coordinating infrastructure and development work, not simply finding a place to call a model API.
The upside depends on whether you need that control plane. A team looking for the shortest path to one hosted endpoint may find the initial setup and configuration more work than necessary. ClearML's free tier gives small teams a concrete way to evaluate the workflow, but confirm the current plan details and any limits that matter to your deployment.
Best fit
AI teams coordinating GPU resources with development and testing.
Builders who need a platform that spans infrastructure management and LLM deployment.
Small teams evaluating an AI operations workflow within the stated free-tier limits.
Limitations
Initial setup and configuration take time.
Plan costs and features may vary, so confirm the current terms.
It may be too much tooling if you only need a simple inference endpoint.
Fluidstack

- AI research teams running large GPU workloads
- Starts at Check vendor pricing
- Usage signal: 144.1K
Fluidstack is the cluster-scale option in this shortlist. It offers access to NVIDIA GPUs including H100, A100, H200, and GB200, with managed infrastructure that can run Slurm and Kubernetes. For research groups or companies running substantial inference alongside training, that managed approach can reduce the burden of assembling and operating a large GPU environment themselves.
It is not the most frictionless choice for a small workload. H200 on-demand pricing requires a request, and reserved clusters have a 30-day minimum term. Those commitments make it especially important to estimate sustained demand and ask for a clear quote before moving production traffic.
Best fit
Research and engineering teams with large, sustained GPU requirements.
Organizations that want managed infrastructure with Slurm or Kubernetes.
Workloads that combine inference with large-scale model training.
Limitations
H200 on-demand pricing requires a request.
Reserved clusters have a minimum 30-day term.
A large managed cluster may be excessive for intermittent or low-volume inference.
More tools to compare
Fireworks AI

- Fast inference for production AI workloads
- Free trial available
- Starts at Check vendor pricing
- Usage signal: 622.4K
Cirrascale Cloud Services

- AI inference across multiple accelerator platforms
- Starts at Check vendor pricing
- Usage signal: 23.1K
SaladCloud

- Cost-conscious AI inference on distributed GPUs
- Free trial available
- Starts at From $0.02/hour
- Usage signal: 646.0K
Vast.ai
- Cost-conscious AI inference workloads
- Starts at GPU rentals from $0.31/hr
- Usage signal: 1.2M
Chutes
- Scalable inference for open-source AI models
- Starts at From $0.0245 per 1M tokens
- Usage signal: 295.1K
Replicate
- Production inference for open-source AI models
- Starts at Check vendor pricing
- Usage signal: 986.6K
Agnes AI
- Multimodal AI API inference
- Free plan available
- Starts at $2/month
- Usage signal: 1.2M
SiliconFlow
- Low-cost, multi-model AI inference
- $1 in free credits
- Starts at From $0.01 per 1M tokens
- Usage signal: 308.8K
Cerebras
- High-speed LLM inference
- Starts at Check vendor pricing
- Usage signal: 802.4K
Lightning AI

- Cloud GPU development and AI model serving
- 35 free GPU hours/month
- Starts at Free; Pro from $30/month (annual)
- Usage signal: 310.6K
Scale AI

- Enterprise AI data and model evaluation
- Starts at Check vendor pricing
- Usage signal: 548.2K
Thunder Compute
- Low-cost GPU inference workloads
- $20 free GPU credit
- Starts at From $0.27/hr
- Usage signal: 143.8K
Featherless.ai

- Serverless Hugging Face model inference
- Starts at From $10/month
- Usage signal: 250.6K
Cerebrium

- Real-time AI apps on serverless GPUs
- $30 free credit
- Starts at Check vendor pricing
- Usage signal: 54.8K
Anyscale

- Distributed AI inference across GPUs and clouds
- $100 in starting credits
- Starts at From $0.00006/min for CPU compute
- Usage signal: 64.8K
Novita AI

- Scalable AI inference with model APIs and serverless GPUs
- Free trial available
- Starts at Check vendor pricing
- Usage signal: 302.9K
FlexAI

- Open-model inference for agent workloads
- $10/month in credits for 3 months
- Starts at From $0.01 per million tokens
- Usage signal: 37.6K
GreenNode

- H100 GPU cloud for AI inference
- Starts at From $2.34/hour
- Usage signal: 59.3K
BasicAI Cloud
- 3D training-data annotation teams
- 50 seats, 100GB, 1,000 model calls free
- Starts at Free
- Usage signal: 24.9K
ZEGOCLOUD

- Real-time voice and video apps
- 10,000 free minutes
- Starts at $0.39 per 1,000 minutes
- Usage signal: 108.6K
RunInfra
- Optimizing and deploying open AI models
- $5 in free credits
- Starts at From $50/month
- Usage signal: 23.4K
Union.ai

- AI inference workflow orchestration
- Free trial available
- Starts at Check vendor pricing
- Usage signal: 24.8K
General Compute

- High-throughput LLM inference
- $200 in free credit
- Starts at Check vendor pricing
- Usage signal: 12.9K
EmpirioLabs AI
- Hosted inference for open and proprietary AI models
- Free plan available
- Starts at From $0.30/1M input tokens
- Usage signal: 32.9K
Gamma.AI

- SaaS data loss prevention
- Starts at Check vendor pricing
- Usage signal: 97.1K
Flatkey AI

- Teams routing multiple AI models through one API
- Starts at $10 prepaid top-up
- Usage signal: 83.1K
Massed Compute

- On-demand GPU compute for AI inference
- Starts at Check vendor pricing
- Usage signal: 32.8K
InsForge
- AI coding agents shipping full-stack apps
- $1 in AI model credits
- Starts at $0/month; Pro from $25/month
- Usage signal: 67.9K
Synexa AI

- Pay-as-you-go AI model inference
- Starts at $0.0015 per image
- Usage signal: 24.8K
Wren AI Cloud
- Natural-language analytics on enterprise data
- Free trial available
- Starts at Check vendor pricing
- Usage signal: 37.7K
CNTXT
- Enterprise AI app building and evaluation
- Starts at Check vendor pricing
- Usage signal: 32.4K
Cloudgov.ai
- Multicloud FinOps cost optimization
- Free trial available
- Starts at Check vendor pricing
- Usage signal: 3.4K
Doubleword
- Low-cost async and batch AI inference
- Starts at From $0.02 per million input tokens
- Usage signal: 48.9K
CloudVerse.AI

- Multicloud FinOps cost visibility and optimization
- Starts at $500/month
- Usage signal: 4.0K
UbiOps

- AI model serving across hybrid and multi-cloud
- Free trial available
- Starts at Check vendor pricing
- Usage signal: 15.5K
Dedalus Labs

- Persistent sandboxes for AI agents
- $20 in starting credits
- Starts at Check vendor pricing
- Usage signal: 35.1K
Sesterce Cloud

- On-demand GPU inference workloads
- Starts at From $0.17/hour
- Usage signal: 12K
Grid.ai

- Machine learning without infrastructure management
- Starts at Check vendor pricing
- Usage signal: 10.5K
Local AI Playground
- Private, offline AI inference
- Free plan available
- Starts at Check vendor pricing
- Usage signal: 5.5K
Clusy
- Cloud ML experimentation and model fine-tuning
- Free plan available
- Starts at $0/month
- Usage signal: 16.0K
SuperAGI

- Developers building autonomous AI agents
- Starts at Check vendor pricing
- Usage signal: 14K
Cognitora
- Secure compute for AI agents
- 5,000 free credits
- Starts at Check vendor pricing
- Usage signal: 2.5K
CloudVerse.ai
- Multicloud FinOps and cloud cost optimization
- 30-day free trial
- Starts at Check vendor pricing
- Usage signal: 4.0K
kluster.ai
- High-volume AI inference workloads
- Starts at Check vendor pricing
- Usage signal: 780
Rose AI

- Financial data discovery and analysis
- Starts at Check vendor pricing
- Usage signal: 10.8K
Infer

- Predictive analytics for RevOps teams
- Free trial available
- Starts at Check vendor pricing
- Usage signal: 2.1K
StackGen
- AI-led infrastructure provisioning and governance
- 1 free user per organization
- Starts at Free
- Usage signal: 10.0K
Hopx

- AI-agent code execution in isolated microVMs
- $200 in free credits
- Starts at From $0.000014/vCPU-second
- Usage signal: 4.7K
DoubleCloud

- Managed real-time analytics data stacks
- Free plan available
- Starts at Check vendor pricing
- Usage signal: 6.2K
Fleak

- Serverless AI data workflows
- Free plan available
- Starts at Check vendor pricing
- Usage signal: 5.0K
Cloudglue
- Turning video libraries into LLM-ready data
- 200 credits, 200 chat requests, 25 minutes indexed
- Starts at $15
- Usage signal: 6.1K
Plat.AI

- No-code real-time predictive modeling
- 14-day trial; 10,000 model requests
- Starts at Check vendor pricing
- Usage signal: 4.2K

Toolhouse

- Deploying LLM agents with built-in tools and memory
- Free plan available
- Starts at Check vendor pricing
- Usage signal: 5.2K
Cortex Labs
- On-chain AI inference in smart contracts
- Starts at Check vendor pricing
- Usage signal: 3.1K
Evoke

- AI app teams needing API-hosted models
- Starts at Check vendor pricing
- Usage signal: 1.2K
Mantlecore AI
- Managed cloud workspaces for AI agents
- $2 free AI credit
- Starts at $19/month
- Usage signal: 1.1K
GPUX

- Autoscaling GPU inference for Dockerized workloads
- Starts at Check vendor pricing
- Usage signal: 68
Censius AI Observability Platform

- Production ML model monitoring
- 14-day free trial
- Starts at Check vendor pricing
- Usage signal: 1.1K
Image Pipeline

- Custom AI image generation pipelines
- Free plan available
- Starts at Check vendor pricing
- Usage signal: 984
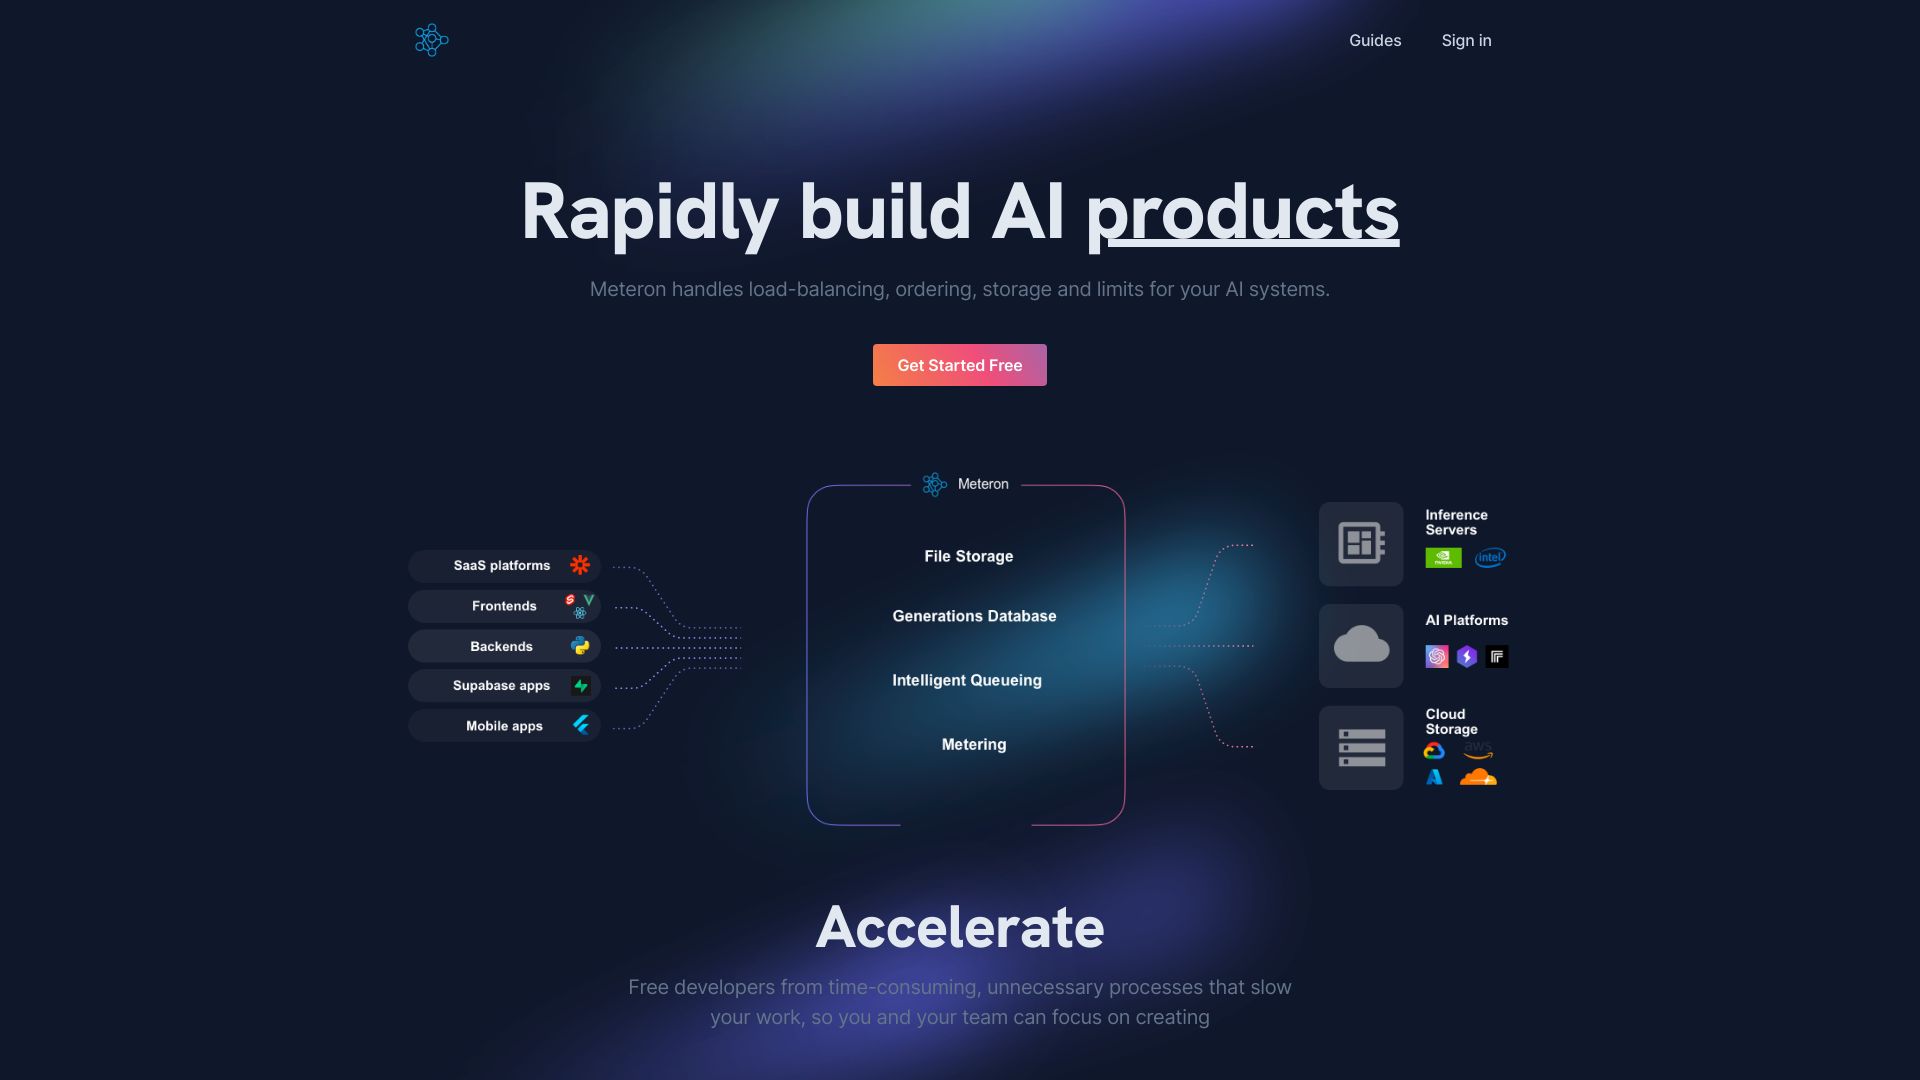
Meteron AI

- AI inference metering and load balancing
- 1,500 image generations/month
- Starts at $39/mo
- Usage signal: 841
Lumino

- LLM fine-tuning on managed GPUs
- Starts at Check vendor pricing
- Usage signal: 451
SkyDeck AI

- Secure AI collaboration for business teams
- Free plan available
- Starts at Check vendor pricing
- Usage signal: 561
Denvr Dataworks
- Managed AI inference workloads
- $1,000 initial compute credit via application
- Starts at Check vendor pricing
- Usage signal: 0
Mystic.ai
- Serverless GPU inference for production ML
- Starts at Check vendor pricing
- Usage signal: 0
EfficientAI
- Multi-cloud AI workload orchestration
- Free plan available
- Starts at Check vendor pricing
- Usage signal: 0
CloudSoul

- Natural-language cloud infrastructure deployment
- Starts at Check vendor pricing
- Usage signal: 0
Novita AI
- Pay-as-you-go Stable Diffusion inference
- 50 free images
- Starts at $0.0015 per image
- Usage signal: 0
BafCloud
- Managing AI models and agents in one cloud platform
- Starts at Check vendor pricing
- Usage signal: 0
QSC Cloud

- On-demand GPU clusters for AI inference
- Starts at Check vendor pricing
- Usage signal: 0
AI Tools 99

- Serverless GPU inference
- Starts at $13.99/year
- Usage signal: 0

Deployo
- Teams deploying models across cloud environments
- Starts at Check vendor pricing
- Usage signal: 0
Taam Cloud
- Multi-model AI API routing
- Free trial available
- Starts at Check vendor pricing
- Usage signal: 0
VeroCloud

- GPU cloud for AI inference workloads
- Starts at From $0.56/hour
- Usage signal: 0
AI Content Generator

- Rapid AI content creation
- Starts at Check vendor pricing
- Usage signal: 0
Starclouds
- Collaborative data science workspaces
- Starts at Check vendor pricing
- Usage signal: 0
Deploifai
- Managing cloud infrastructure for ML projects
- Free plan available
- Starts at Free; pay cloud provider costs
- Usage signal: 0
Varo Cloud

- Unified generative media inference APIs
- Starts at From $0.0201 per second
- Usage signal: 0
阿里云 (Aliyun)
- Budget-conscious ECS hosting for startups
- Starts at Check vendor pricing
- Usage signal: 0
DataCrunch

- Chaining AI models into no-code workflows
- Starts at Check vendor pricing
- Usage signal: 0
SnowBrain

- Conversational Snowflake data analysis
- Starts at Check vendor pricing
- Usage signal: 0
Incribo

- Building open-source AI infrastructure
- Starts at $15/month
- Usage signal: 0
AI Pricing
- Comparing AI model API prices
- Starts at Check vendor pricing
- Usage signal: 0
ClearML
- Enterprise LLM inference deployment
- Free plan available
- Starts at Check vendor pricing
- Usage signal: 0
Google Cloud

- Cloud ML pipelines and application workloads
- Starts at Check vendor pricing
- Usage signal: 0
TAHO by Opnbook
- High-throughput AI inference on hybrid infrastructure
- Starts at Check vendor pricing
- Usage signal: 0
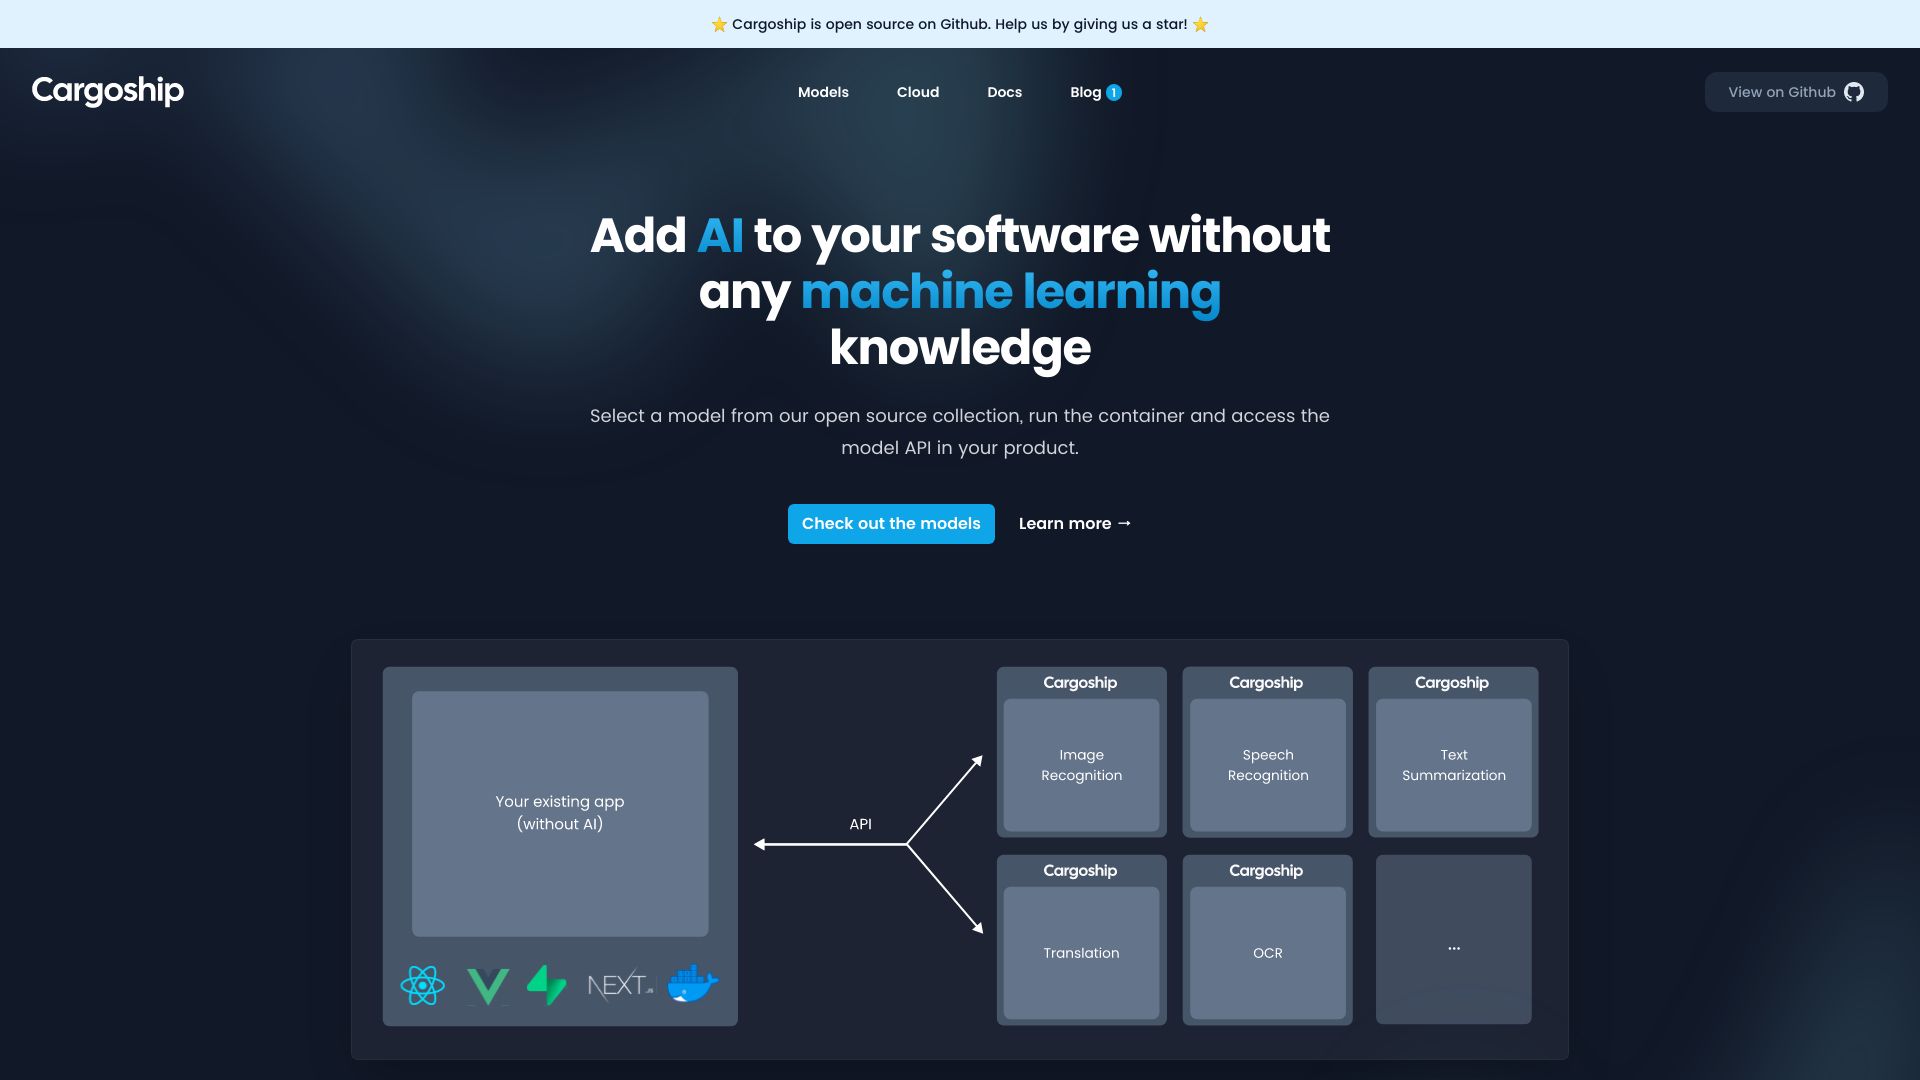
Cargoship
- Self-hosting packaged AI models
- Starts at Check vendor pricing
- Usage signal: 0
GiGOS

- Comparing responses across AI models
- Starts at $10 minimum credit top-up
- Usage signal: 0
ThirdAI

- Private AI inference on CPU infrastructure
- Free plan available
- Starts at Check vendor pricing
- Usage signal: 0
AgentSphere

- Secure cloud sandboxes for AI agent code execution
- Free trial available
- Starts at Check vendor pricing
- Usage signal: 0
Which tool should you try first?
Start with Atlas Cloud if you want broad model choice and multimodal inference behind one API. Try Nebius AI Cloud if your decision revolves around NVIDIA GPU capacity, scaling, or fine-tuning. Choose Deep Infra for a simpler pay-per-use API and a $10 monthly free-usage allowance. If your workflow is already ComfyUI-based, RunningHub is the more natural first test; for diffusion-heavy product work, put fal.ai on the shortlist instead.
Before moving beyond a prototype, run a representative workload. Measure latency and throughput with your own prompts, payload sizes, and concurrency; then compare the bill at realistic usage. A headline starting price rarely captures the full cost of production inference.
Full comparison table
| Rank | Tool | Score | Best for | Free access | Starting price |
|---|---|---|---|---|---|
| #1 | Atlas Cloud | 93/100 | Multimodal inference through one API | Not listed | From $0.01/PIC for Z-Image-Turbo LoRA |
| #2 | Nebius AI Cloud | 93/100 | NVIDIA GPU infrastructure and fine-tuning | Not listed | NVIDIA H200 GPU: $2.30 |
| #3 | Deep Infra | 93/100 | Simple, pay-per-use inference API | $10 free usage per month | Check vendor pricing |
| #4 | Together AI | 93/100 | Inference plus fine-tuning | Not listed | Check vendor pricing |
| #5 | RunningHub | 93/100 | Cloud ComfyUI workflows | Not listed | Check vendor pricing |
| #6 | BytePlus | 93/100 | Enterprise multimodal AI | Free image and video tokens | Bandwidth: $11.50/month/Mbps |
| #7 | RunPod | 93/100 | GPU rentals and serverless inference | Not listed | MI300X from $2.49/hour |
| #8 | fal.ai | 93/100 | Diffusion and generative-media inference | Not listed | Check vendor pricing |
| #9 | ClearML | 93/100 | GPU resource and workflow management | Free for 3 users; 100GB storage; 1M API calls/month | Check vendor pricing |
| #10 | Fluidstack | 92/100 | Managed, large-scale GPU clusters | Not listed | Check vendor pricing |
Best by use case
| Need | Shortlist pick | Why it fits |
|---|---|---|
| One API across multiple modalities | Atlas Cloud | Covers chat, reasoning, image, audio, and video, with a catalog of 300+ models. |
| NVIDIA GPU infrastructure and fine-tuning | Nebius AI Cloud | Pairs GPU accelerators and InfiniBand with AI Studio for fine-tuning. |
| A straightforward API with a free usage allowance | Deep Infra | Offers simple API-based inference and $10 in free monthly usage. |
| Cloud ComfyUI or diffusion workflows | RunningHub / fal.ai | RunningHub suits ComfyUI users; fal.ai focuses on diffusion inference and training APIs. |
Atlas Cloud vs Nebius AI Cloud vs Deep Infra
Atlas Cloud is the broadest fit when one API needs to cover several modalities. Nebius is the stronger infrastructure choice when GPU configuration and fine-tuning matter. Deep Infra keeps the workflow simpler for developers who want pay-per-use API access. Their scores tie, so decide by architecture, operating effort, and a measured cost test rather than the ranking number alone.
| Atlas Cloud | Nebius AI Cloud | Deep Infra | |
|---|---|---|---|
| Core approach | Unified multimodal API | GPU cloud and AI development | Simple inference API |
| Standout | 300+ models across modalities | NVIDIA accelerators, InfiniBand, AI Studio | Pay-per-use and $10 monthly free usage |
| Watch out for | Usage-based billing | Technical infrastructure management | Payment setup and usage thresholds |
Best free cloud platform for AI inference
Deep Infra is the clearest free starting point here: it lists $10 in free usage per month. ClearML also has a defined free tier for teams up to three users, with 100GB storage and one million API calls per month. BytePlus lists free image and video tokens. Check current eligibility and limits with each vendor; a free allowance is not a promise of free production-scale inference.
Pricing: what you actually pay for
These platforms mix per-use API pricing, GPU-hour rates, and infrastructure quotes, so compare the same workload rather than headline figures. Deep Infra's listed free usage is $10 per month; Atlas Cloud lists a task-specific $0.01/PIC offer. Nebius and RunPod provide GPU price signals, while Fluidstack, Together AI, and others may require configuration checks or a vendor quote. Verify current prices, billing units, and minimum terms before committing.
When to skip these tools
Skip a full cloud platform if your workload is small, intermittent, and already runs reliably on an existing provider. Avoid GPU rentals when utilization is low enough that idle capacity erases the hourly-rate advantage. If you need a no-code end-user app rather than developer infrastructure, start with a purpose-built app tool. And if pricing cannot be mapped to your request volume, do not route production traffic until you have a measured cost estimate.
How we scored the list
We ranked 99 candidates for their fit with AI inference, considering model and GPU access, deployment options, developer workflow, pricing signals, and stated limitations. The featured 10 are the strongest shortlist matches for this category, not a claim that every product suits every workload. Scores are comparative; validate latency, reliability, and live pricing against your own use case.
Who reviewed this guide
FAQ
It provides some combination of model APIs, GPU compute, deployment tools, or managed infrastructure for running trained models and returning predictions. Platforms differ in how much serving and operations work they handle for you.